Licensed to be used in conjunction with basebox, only.
// documents
Working with PDFs
PDFs are the most common document format in basebox. This page explains what happens to text PDFs and scanned PDFs, how to work with large documents and why a PDF is sometimes not processed.
Two kinds of PDF
Text PDFs – produced from Word, a report generator or a browser. The text is contained as text (you can select it in a PDF reader). basebox extracts it directly.
Scanned PDFs – pages that exist as images: scans, faxes, photographed documents. There is no selectable text. basebox reads the content by text recognition (OCR) – accelerated where a GPU is available, otherwise on the CPU. You do not need to do anything for this; both kinds are uploaded the same way.
Mixed forms work too: a text PDF with embedded scanned attachments, for example.
Uploading and querying a PDF
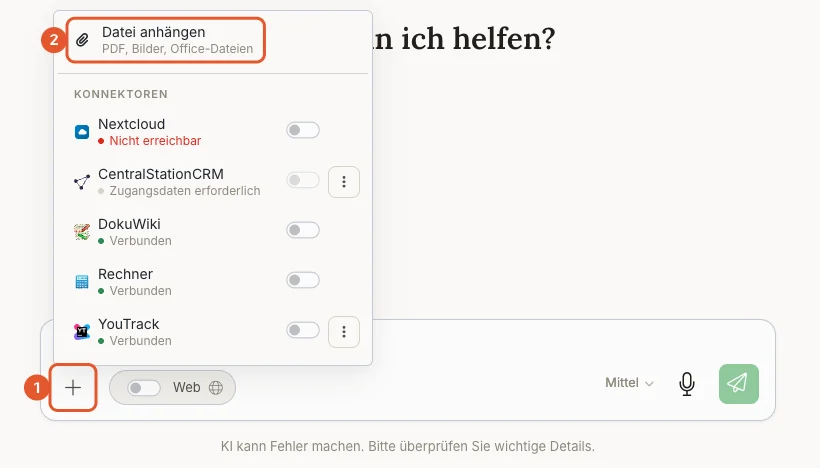
- Drag the PDF into the chat or click the "+" icon and then Attach file (in the chat: up to 10 MB per file).
- Wait for the upload confirmation.
- Ask a specific question: "Which notice periods does the contract state?" rather than "What does it say?"
For documents you need again and again, put them into an app's knowledge base. Higher limits apply there, and answers come with citations down to the source passage.
Large PDFs
In the chat, the amount of text counts, not the file size. As a guideline, about 50 pages fit into a chat; a densely printed 30-page PDF can already be too much. If a processing error or "context window reached" appears, three approaches help:
- Split – extract only the relevant pages, or split the document into sections and work through them one after another.
- New chat – a long-running chat has less room left. A new chat starts with a full context window.
- App knowledge base – there, documents are broken into sections and searched selectively instead of being loaded into the context window in full. That is the right approach for manuals, guidelines and collections.
Background: Context window.
When a PDF is not processed
Scanned PDFs without selectable text are not a problem – they are read via OCR. Only encrypted or corrupted files are, and too much text for the context window. Messages, causes and solutions are listed in a table under Solving upload problems → PDF files.
Name the part of the document you mean
Tips for good results
- Say in your question which part of the document you mean: "in the payment terms section", "on the last two pages".
- For long documents, first ask for an outline, then ask targeted follow-up questions.
- Check numbers and quotations in the original – with an app knowledge base via the source chip, which shows you the passage.
Note
From a PDF, basebox can create new documents on request – for example a summary as a Word file or a table as Excel. See Generating documents.
Frequently asked questions
Does basebox recognise tables in PDFs? Yes, tables are extracted as text with their structure. For calculations, an Excel file is better suited.
Are images in a PDF analysed? Text in images is read via OCR. Pure graphics without text yield no usable content.
Can I compare several PDFs at once? Yes, attach both and ask: "How do version A and version B differ?" Keep the context window in mind.
Next step: Converting CSV to Excel · Working with images
Need help? Contact support